A little more about the project
a simple node.js utility i built for the gallery page on this website. instead of painstakingly adding every photo and its metadata to the database, i can simply add photos to a Google Photos album (where i store all of my photos anyways) and let the scraper handle the rest
it retrieves photos, extracts details, and stores everything in Supabase, including optimised image files ready to use as previews on the website. this makes updating the gallery really easy, as simple as adding photos to an album. pair this with a cronjob that runs it every 3 days on your server, and you're set!
A closer look at how it works
the scraper reads a shared Google Photos album and compares the contents from the database to the album itself. photos that have been added are skipped, and photos that aren't in the album are automatically deleted from the table. for each new photo, it collects the available metadata, including dimensions, timestamps, descriptions, and camera information. the metadata is then saved to a Supabase database, while the image is resized and converted to .webp files before being uploaded to a storage bucket
using sharp, the scraper resizes images to a maximum width of 1200 pixels without enlarging smaller images, then converts them to .webp at 80% quality. it keeps the stored images more managable for previews on the gallery page. when you click on an image, it downloads the full resolution image by connecting to a (currently private) Cloudflare Worker that proxies and caches each photo, so i don't get flagged for botting hehe
What I learned
figuring out how Google returns JSON data from the albums was one of the tricky parts of the project, because NONE of the keys were named properly and just returned one letter key with seemingly random properties in random orders. i used GitHub's Copilot to help understand what the fetched pages were returning and how the data was organised, comparing it to what i see in the web interface.
the main limitation is that Google doesn't provide a public API for this particular workflow, so the scraper depends on GOogle's internal page structure which can change without warning and break the whole process
Some images from this project
You may also want to check this out...
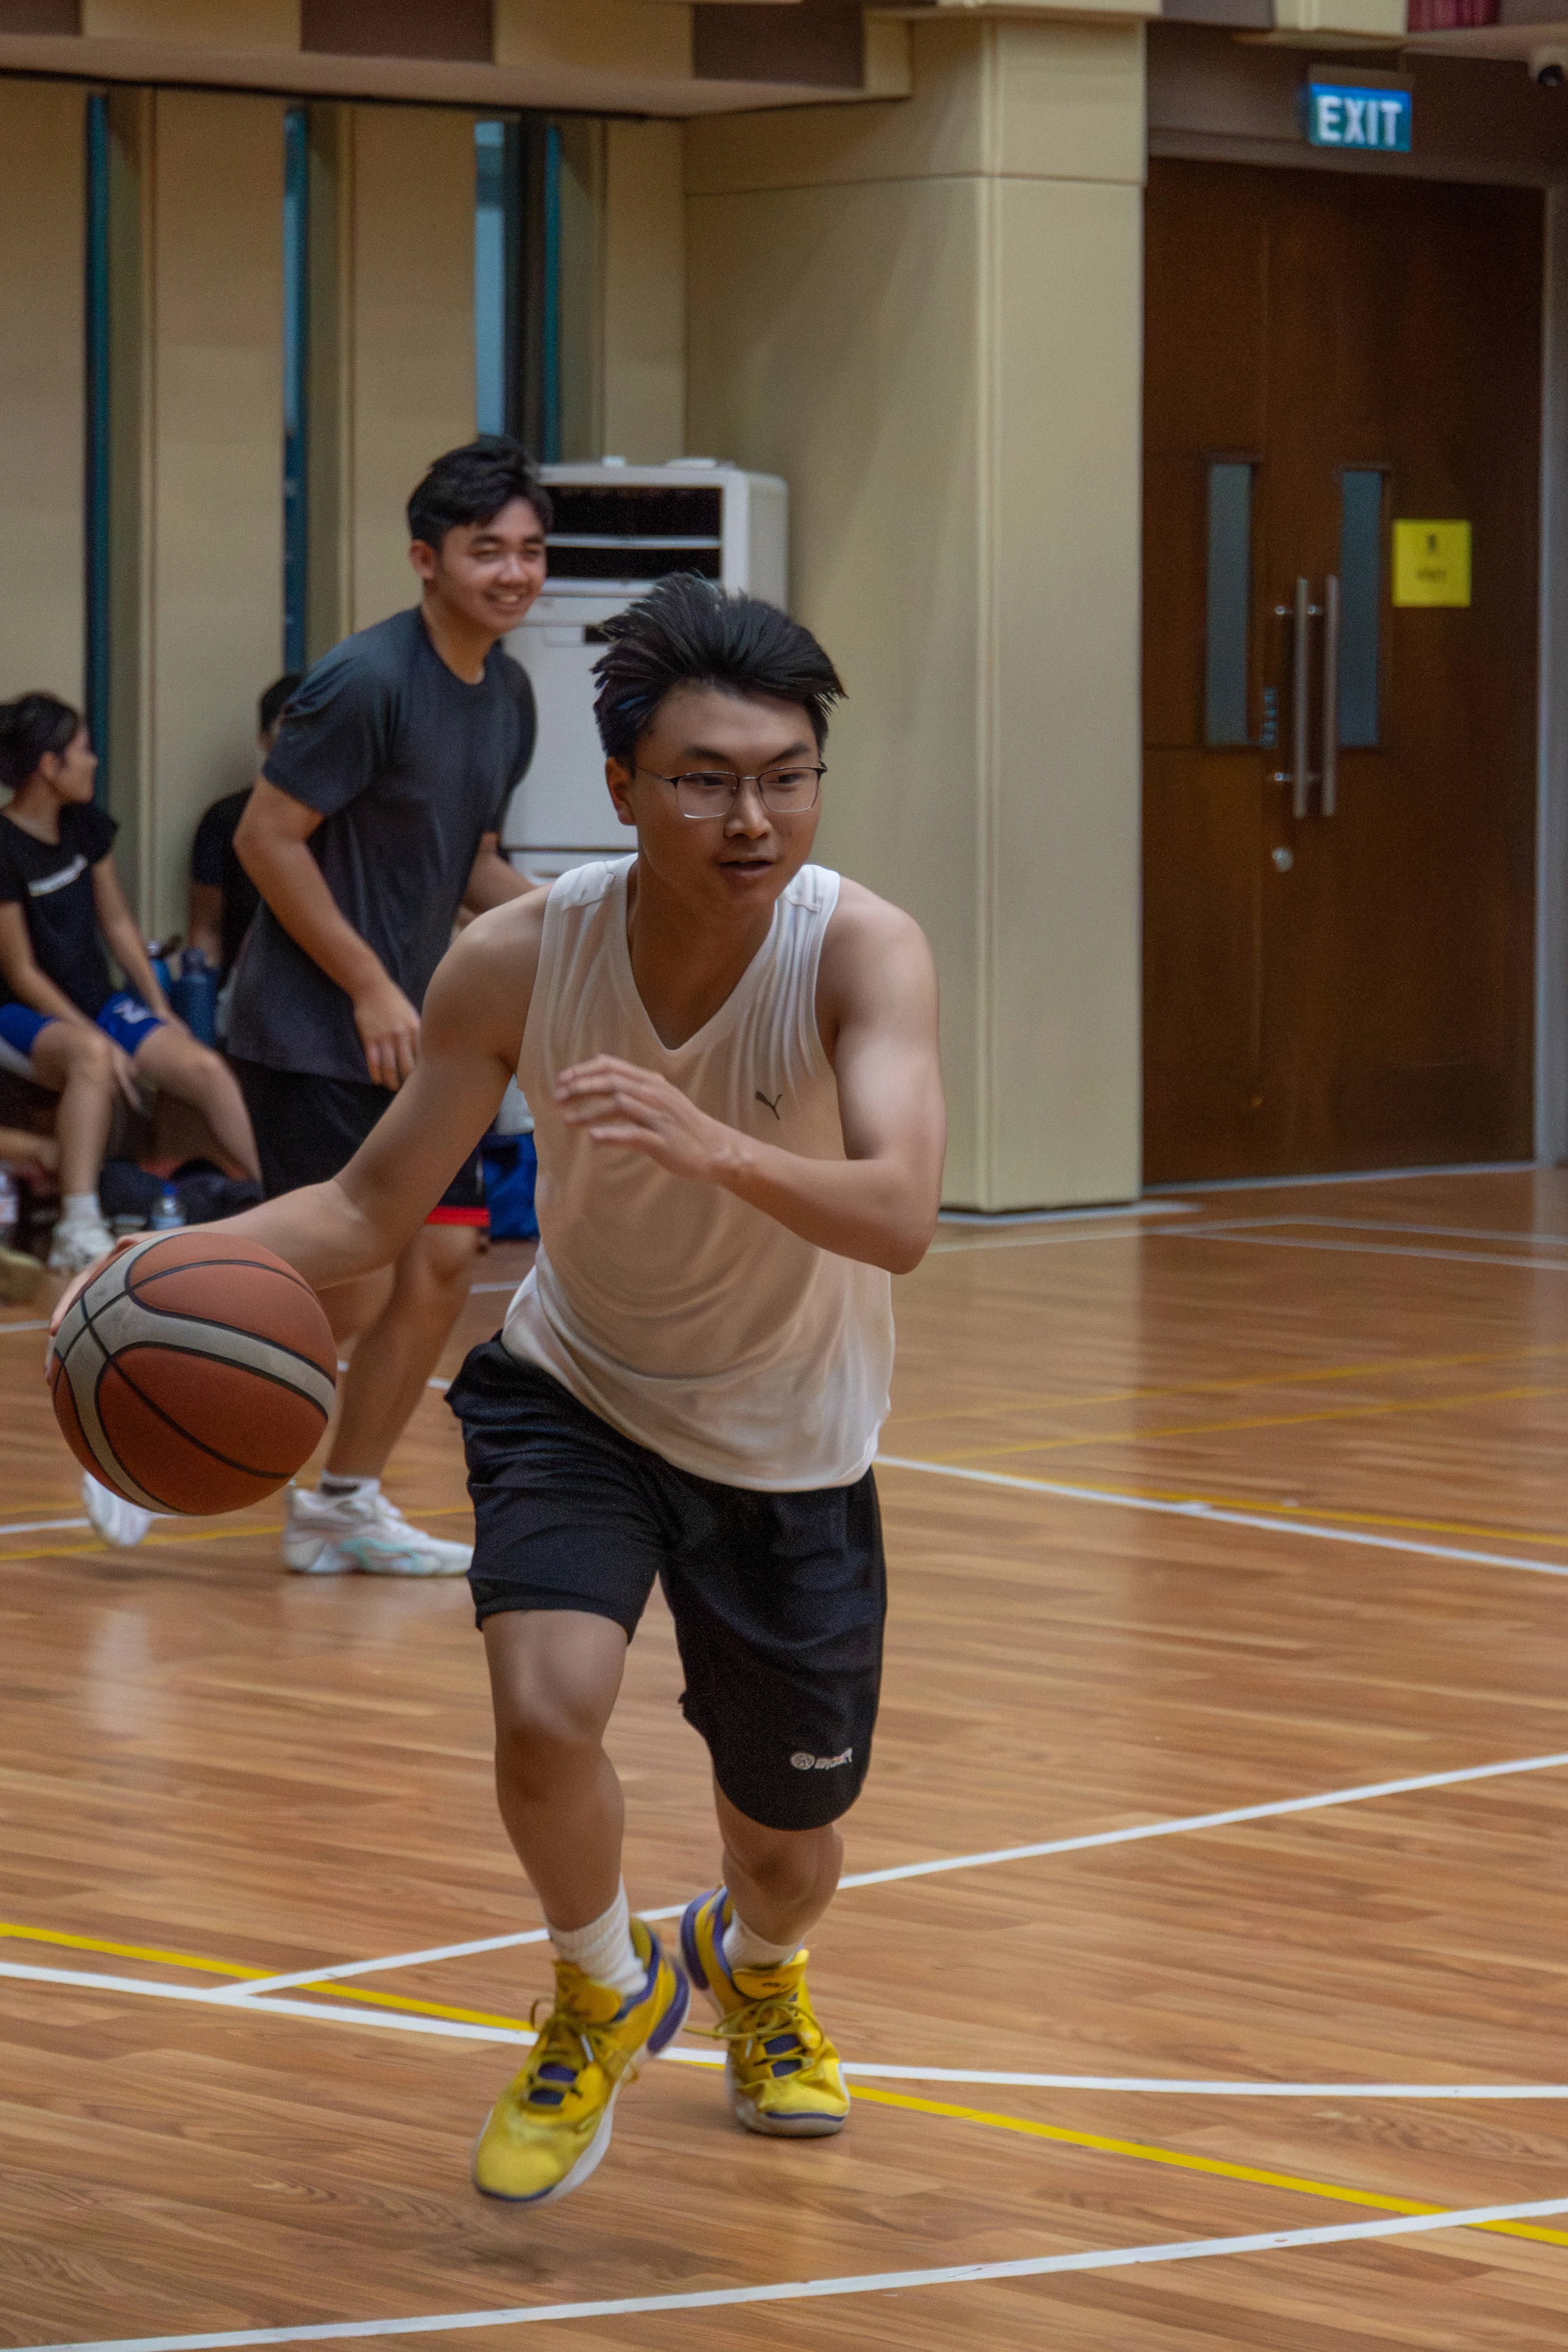
James' Eighteenth Birthday
Birthday Celebration
photos from James' Eighteenth Birthday celebration, covering the party at the basket field
Nicole's Sweet Seventeenth
Birthday Celebration
collection of photos capturing Nicole's seventeenth birthday, from portraits to candid moments throughout the celebration
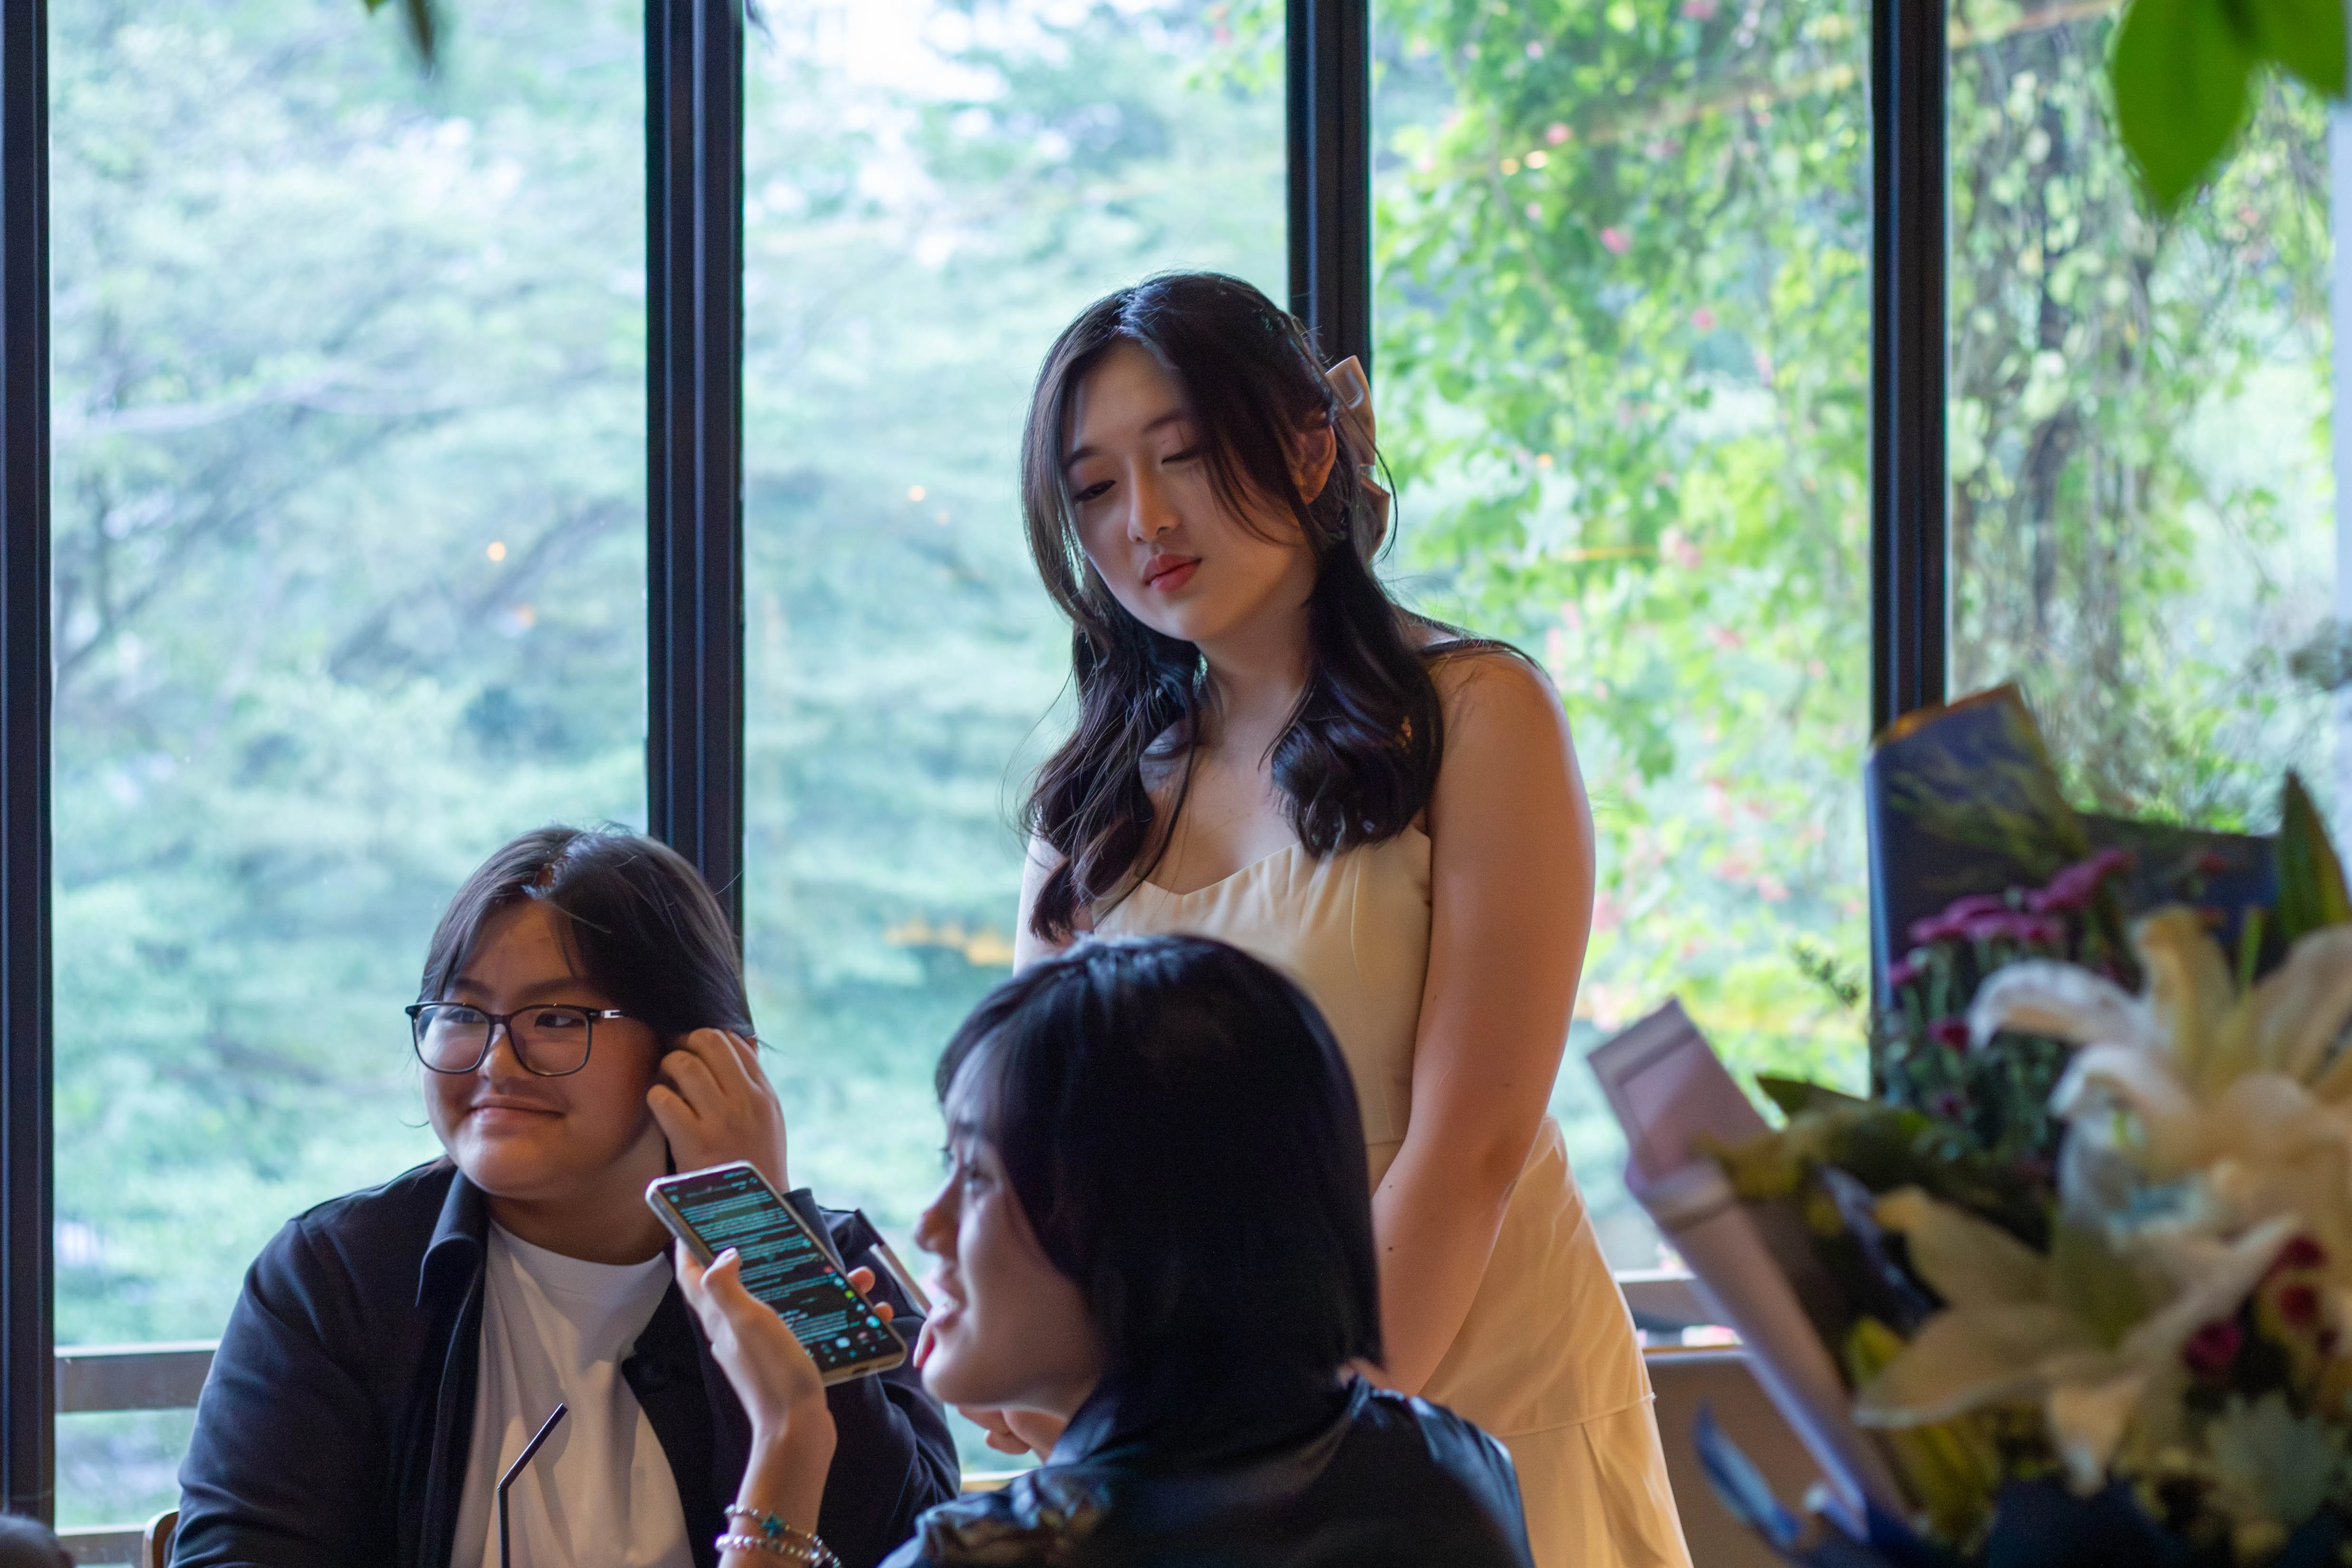
Nadine's Sweet Seventeenth
Birthday Celebration
series of photos capturing Nadine's seventeenth birthday